Credit Card Fraud Detection
Last updated:
A comparative study of ten models on credit card fraud detection: five classical approaches — logistic regression, a decision tree, random forest, SVM and XGBoost — against five neural architectures — an MLP, a deeper feedforward network, a 1D CNN, an LSTM and an autoencoder.
The dataset holds 284,807 anonymized transactions, of which 492 are fraudulent: about 0.17%. The central methodological choice was to leave that imbalance alone. Most comparisons resample first, oversampling fraud or undersampling legitimate transactions, which flatters the scores that follow. Here the imbalance is handled with class weights instead, and every model is scored on the same held-out test set of 85,443 transactions, 148 of them fraud. That keeps the results honest about deployment conditions, where fraud stays rare no matter how the training set was balanced. Features are scaled on training data only, seeds are fixed, and a single script reproduces every number below.
The autoencoder was treated differently from the rest: trained only on legitimate transactions and used as an unsupervised anomaly detector, flagging anything that reconstructs worse than 95% of the training data. That covers the case where labels don’t exist, which is the common one — fraud is usually confirmed long after a transaction clears, if it is confirmed at all. Without ever seeing a fraud label it still caught 80.4% of fraud, at the cost of 4,302 false alarms.
Results
Precision, recall and F1 are for the fraud class at a 0.5 threshold.
| Model | Precision | Recall | F1 | ROC AUC | PR AUC | False alarms | Missed |
|---|---|---|---|---|---|---|---|
| Logistic Regression | 0.067 | 0.878 | 0.125 | 0.968 | 0.705 | 1,806 | 18 |
| Decision Tree | 0.773 | 0.669 | 0.717 | 0.834 | 0.518 | 29 | 49 |
| Random Forest | 0.711 | 0.797 | 0.752 | 0.968 | 0.798 | 48 | 30 |
| SVM | 0.310 | 0.669 | 0.424 | 0.964 | 0.403 | 220 | 49 |
| XGBoost | 0.233 | 0.851 | 0.366 | 0.974 | 0.739 | 415 | 22 |
| MLP | 0.096 | 0.858 | 0.172 | 0.941 | 0.672 | 1,202 | 21 |
| DNN | 0.049 | 0.872 | 0.093 | 0.947 | 0.689 | 2,494 | 19 |
| CNN | 0.059 | 0.865 | 0.110 | 0.953 | 0.678 | 2,049 | 20 |
| LSTM | 0.082 | 0.831 | 0.149 | 0.932 | 0.564 | 1,380 | 25 |
| Autoencoder | 0.027 | 0.804 | 0.052 | 0.926 | 0.290 | 4,302 | 29 |
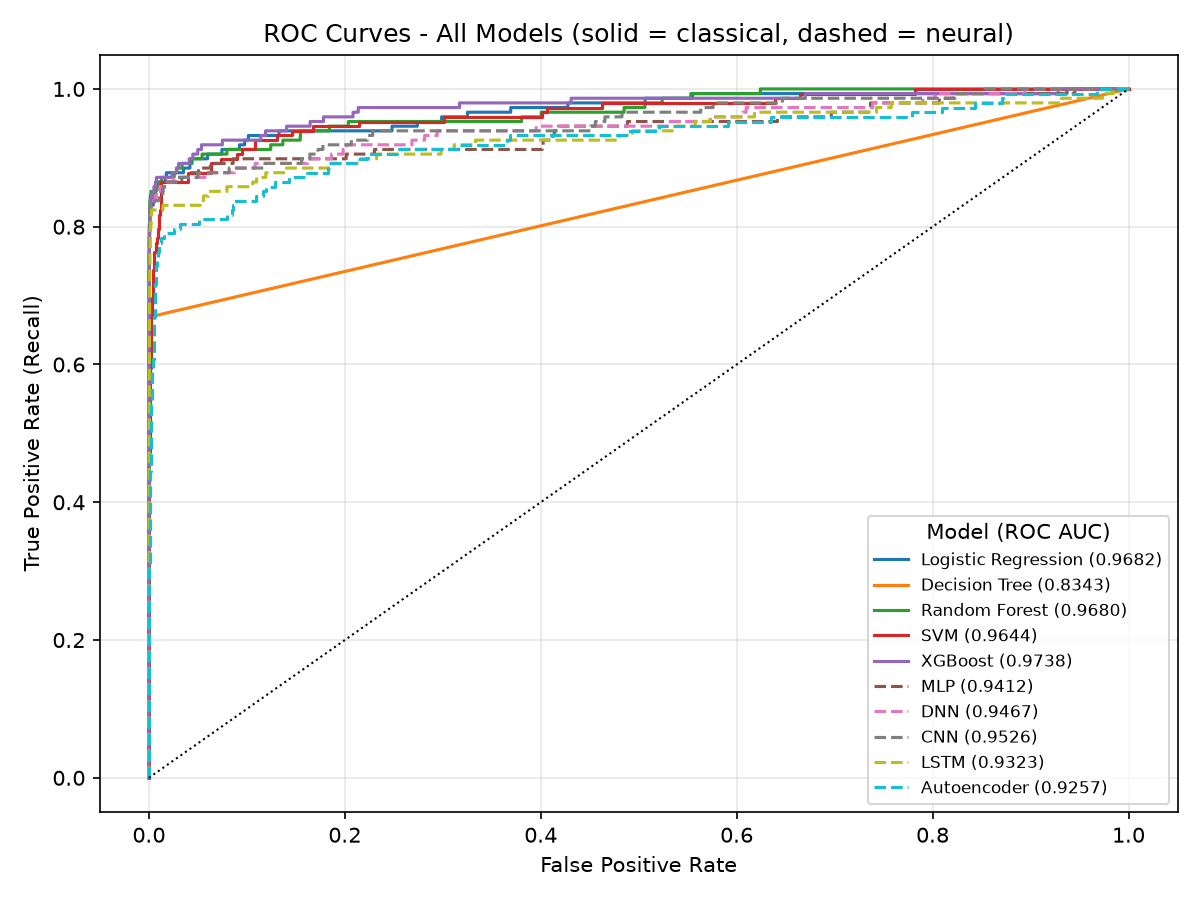
The classical ensembles came out ahead. XGBoost ranked fraud best, with a ROC AUC of 0.974, and trained in about two seconds. Random Forest gave the best balance of precision and recall, with an F1 of 0.752 and only 48 false alarms across 85,000 transactions. The neural networks caught a similar share of fraud but raised far more false alarms doing it, ranked fraud less well, and took 20 to 160 times longer to train than XGBoost. Treating the features as an image or a sequence, as the CNN and LSTM do, brought nothing to tabular data.
Accuracy says almost none of this. Every model scores above 94%, the DNN 97% while flagging 2,494 legitimate customers. Precision and recall at a single threshold also depend as much on the class weighting as on the model: logistic regression has 6.7% precision at 0.5 but a respectable PR AUC of 0.705, so a higher threshold would trade a little recall for far fewer false alarms. Where to set it depends on whether a missed fraud or a blocked customer costs more, and that is a business question rather than a modeling one.
Interpretability pointed the same way. In finance a decision has to be explainable to a customer, a regulator or the analyst reviewing the flag. Tree ensembles give feature importances and can be explained per prediction with tools like SHAP, where a CNN or LSTM is a black box. On this dataset the best models were also among the more explainable, so there was no trade-off to make.